PyPI-only quickstart
Core estimation requires Python 3.10–3.14 and does not load weights. Training qualification uses Python 3.12. Start in a new working directory, outside a clone.
Windows PowerShell (verified natively)
py -3.12 -m venv .venv
.\.venv\Scripts\Activate.ps1
$env:PYTHONUTF8 = "1"
python -m pip install --index-url https://pypi.org/simple canifinetune==0.4.1
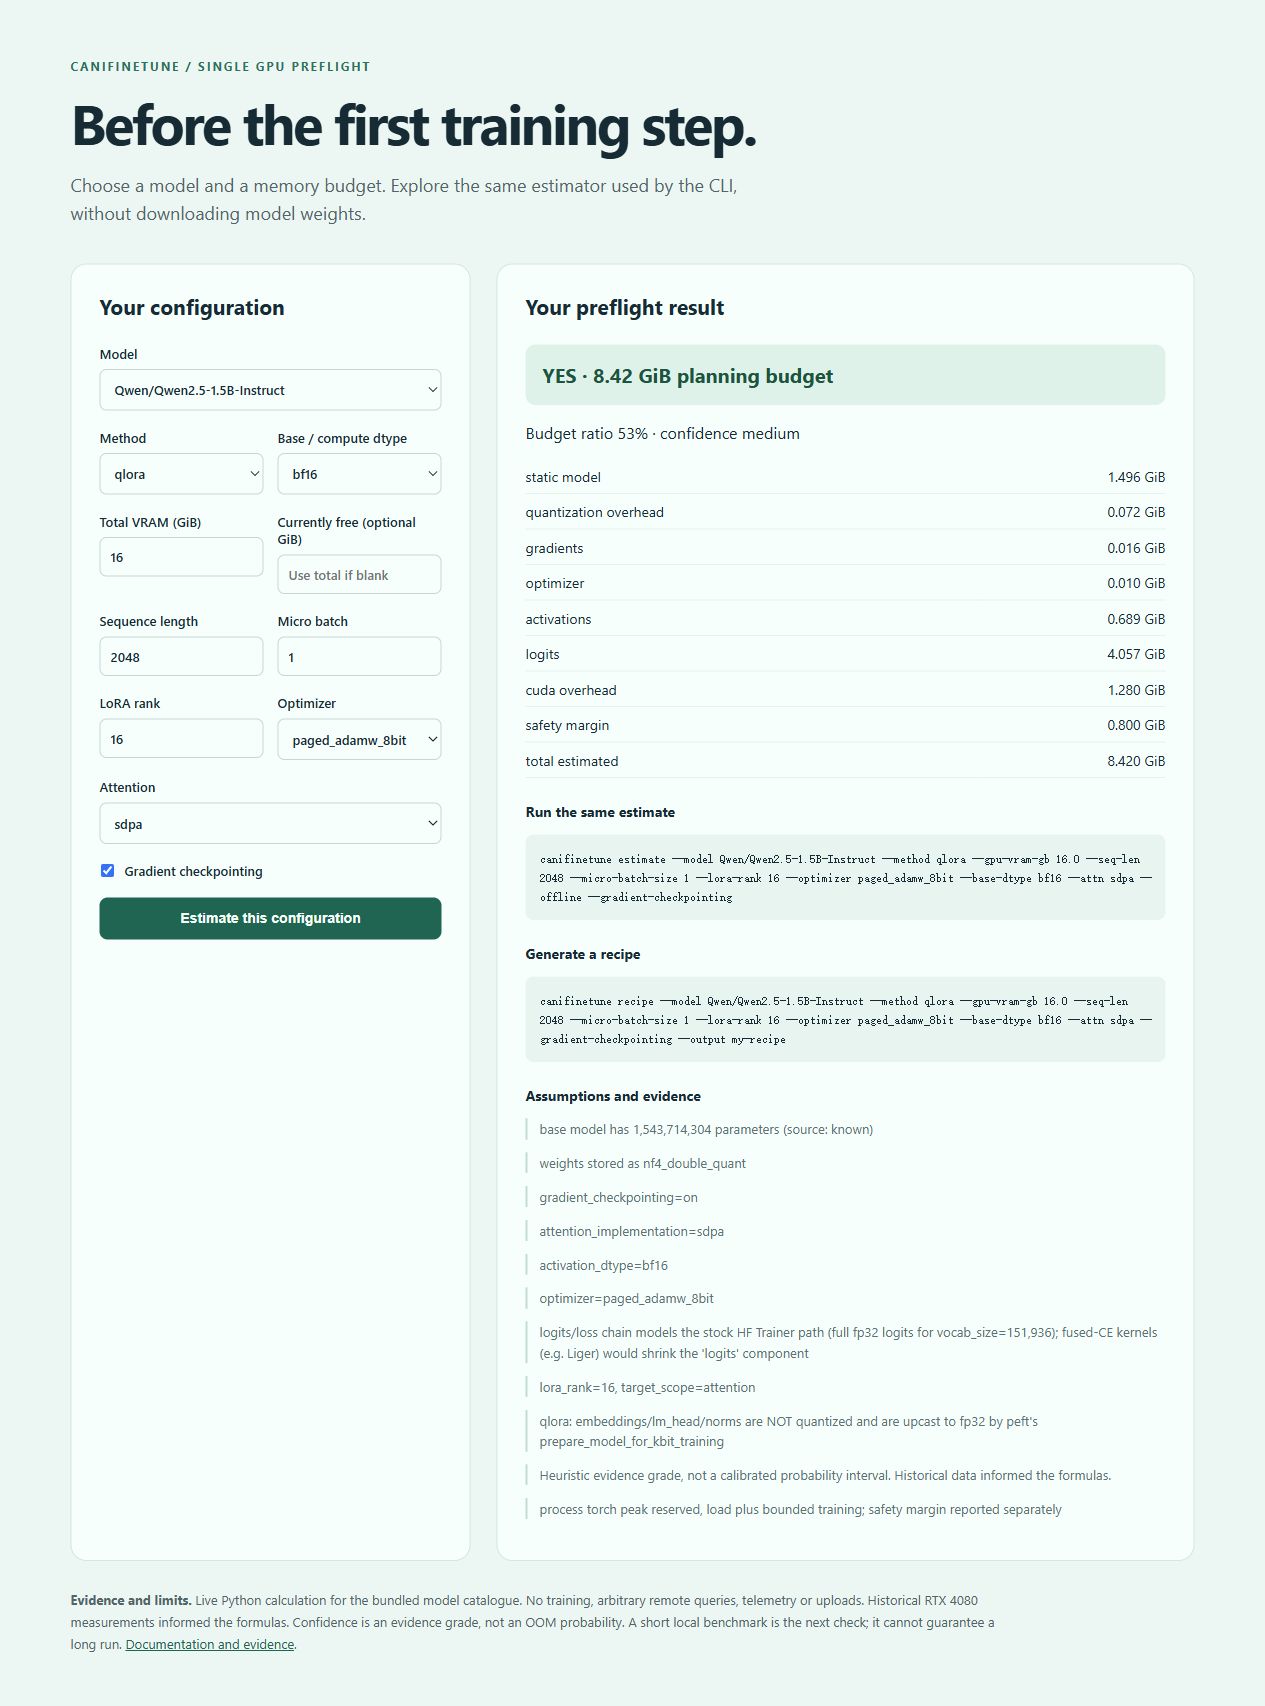
canifinetune estimate --model Qwen/Qwen2.5-1.5B-Instruct --method qlora --gpu-vram-gb 16 --seq-len 2048 --offline
canifinetune demo
Open the printed loopback URL. Stop the server with Ctrl+C to continue in the same
terminal, or use a second terminal with this environment activated. The estimate
is 8.420 GiB, yes, heuristic confidence medium; it is a planning budget.
For the verified RTX 4080 CUDA path (compatible NVIDIA driver required):
python -m pip install torch==2.6.0 --index-url https://download.pytorch.org/whl/cu124
python -m pip install -c https://raw.githubusercontent.com/DaoyuanLi2816/can-i-finetune-this/v0.4.1/constraints/train-recommended.txt "canifinetune[train]==0.4.1"
canifinetune recipe --model Qwen/Qwen2.5-0.5B-Instruct --revision 7ae557604adf67be50417f59c2c2f167def9a775 --method qlora --seq-len 256 --max-steps 2 --grad-accum 1 --output my-recipe
python my-recipe/train.py --config my-recipe/config.yaml
python my-recipe/eval_smoke.py --output-dir my-recipe/output --max-new-tokens 8
The first training command downloads approximately 988 MB of weights plus small metadata/tokenizer files. It performs two genuine updates with paged AdamW8bit, saves an adapter and reloads the pinned base plus adapter for generation. The bundled instruction samples fit sequence 256 for this tokenizer; replacement data may fail the default no-truncation check. This is a pipeline demonstration, not a quality evaluation. Check current free GPU memory before loading weights.
Linux shell / WSL shell
python3.12 -m venv .venv
source .venv/bin/activate
export PYTHONUTF8=1
python -m pip install canifinetune==0.4.1
canifinetune estimate --model Qwen/Qwen2.5-1.5B-Instruct --method qlora --gpu-vram-gb 16 --offline
python -m pip install torch==2.6.0 --index-url https://download.pytorch.org/whl/cpu
python -m pip install -c https://raw.githubusercontent.com/DaoyuanLi2816/can-i-finetune-this/v0.4.1/constraints/train-recommended.txt "canifinetune[train]==0.4.1"
canifinetune smoke-model --output tiny-local
canifinetune recipe --model tiny-local --method lora --device cpu --base-dtype fp32 --optimizer adamw_torch --seq-len 128 --max-steps 2 --grad-accum 1 --offline --output cpu-recipe
python cpu-recipe/train.py --config cpu-recipe/config.yaml
python cpu-recipe/eval_smoke.py --output-dir cpu-recipe/output --max-new-tokens 2
Linux CPU qualification runs in CI. WSL GPU and macOS training have not been qualified for 0.4.0. A CPU wheel cannot run CUDA QLoRA. For Windows CPU use the same CPU install and smoke commands after the PowerShell environment setup. The tiny model is random and created locally; this smoke needs no Hub weights.
Interpret and diagnose
output/run.json must have status: success and the requested update count.
Full training saves model; LoRA/QLoRA saves adapter. Reload checks must also
exit zero. Existing output directories are protected; select a fresh directory
for another run. Inference artifacts do not include full training resume state.
bench uses full-length synthetic all-token labels and can consume more memory
than short sample data. Compare its process reserved peak with
estimated_process_reserved_gb, excluding the separate safety allowance. Device
free memory is a different scope. See validation,
training contract and troubleshooting.