CANIFINETUNE / SINGLE GPU PREFLIGHT
Can I fine-tune this LLM on my GPU?
Make a memory plan before loading weights. Then generate a recipe and check it with a real local run.
Plan
Estimate weights, gradients, optimizer state, activations and loss memory. Core needs no torch and downloads no model weights.
Execute
Generate a versioned Transformers/PEFT recipe, perform real updates, save a model or adapter, and reload it for generation.
Measure
Compare the planning budget with a scoped process peak. Keep outcomes, effective settings and the source of evidence visible.
One install, a useful first answer
python -m pip install canifinetune==0.4.1
canifinetune estimate --model Qwen/Qwen2.5-1.5B-Instruct --method qlora --gpu-vram-gb 16 --seq-len 2048 --offline
canifinetune demo
8.420 GiB · YES against 16 GiB · heuristic confidence medium. The estimate is a planning budget, not a promise that a long training run cannot OOM. Create a virtual environment first; platform-specific instructions cover native Windows and Linux/WSL.
Explore the same estimator in your browser
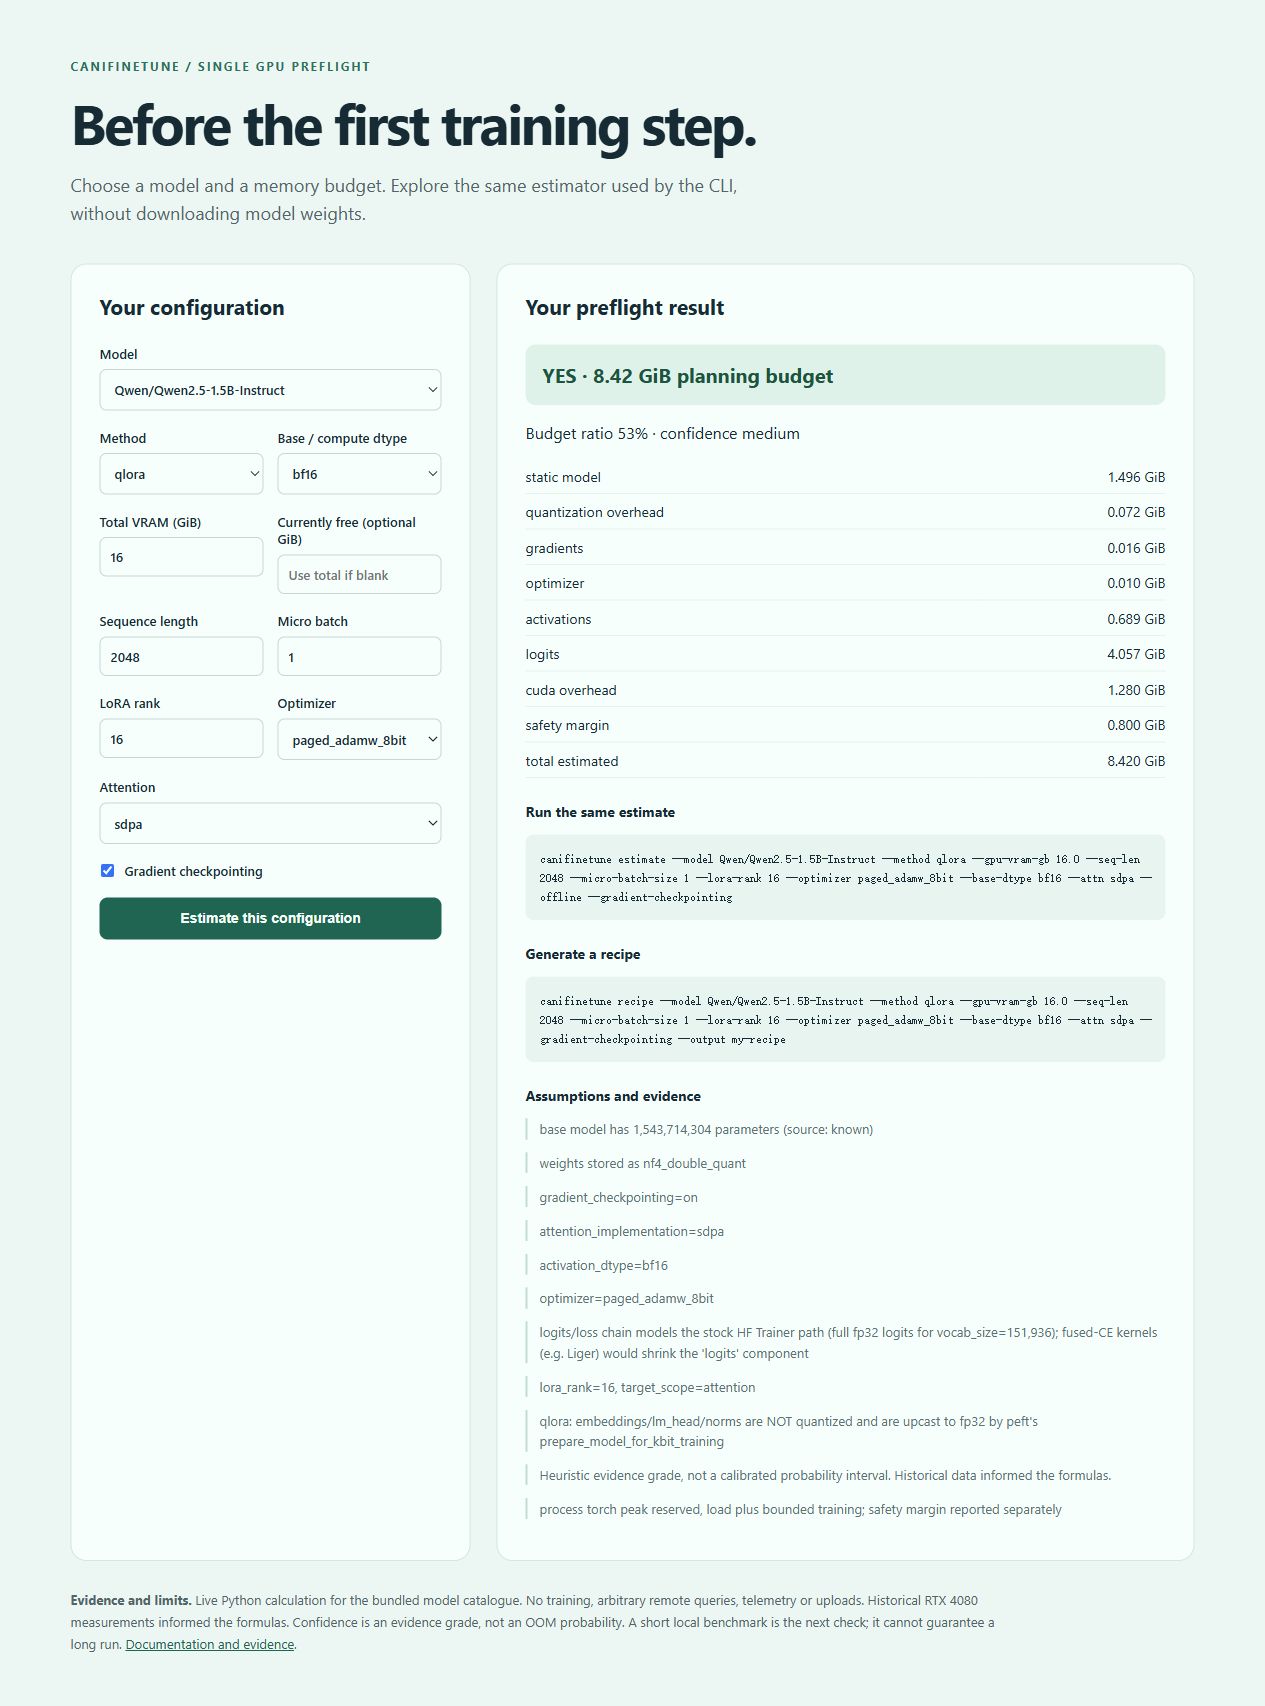
canifinetune demo serves a local page at http://127.0.0.1:8765.
It does not train, query arbitrary URLs, upload data or require an account.
This documentation site contains guides and recorded examples; the live estimator
runs on your machine.
From plan to evidence

Architecture explains the shared contract. Training semantics describe system/multi-turn processing, labels, truncation and save/reload behavior.
What the evidence supports
Four prospective 0.5B LoRA/QLoRA observations on one Windows RTX 4080 succeeded with reserved peaks of 1.666–2.398 GiB. Their old/new predictions are identical: 46.2% MAPE, all four overestimates, no demonstrated accuracy improvement. This small frozen cohort is distinct from historical fitting data and package execution checks. It does not establish cross-GPU accuracy or a general OOM risk.
Prospective report and raw records · Historical development evidence · Compatibility
Help make the next run easier
Contribute a documented model-family check, a reproducible bounded measurement, or a first-use improvement. Export is opt-in, redacted and manual; community records remain unreviewed until checked.